01

Infrastructure & cloud review
Map servers, cloud resources, networks and dependencies. Identify configuration, capacity and ownership gaps before changing the environment.
Keep your business running on systems your team can manage. Bring cloud infrastructure, monitoring, access and recovery into one operating plan, with clear responsibilities and practical support.
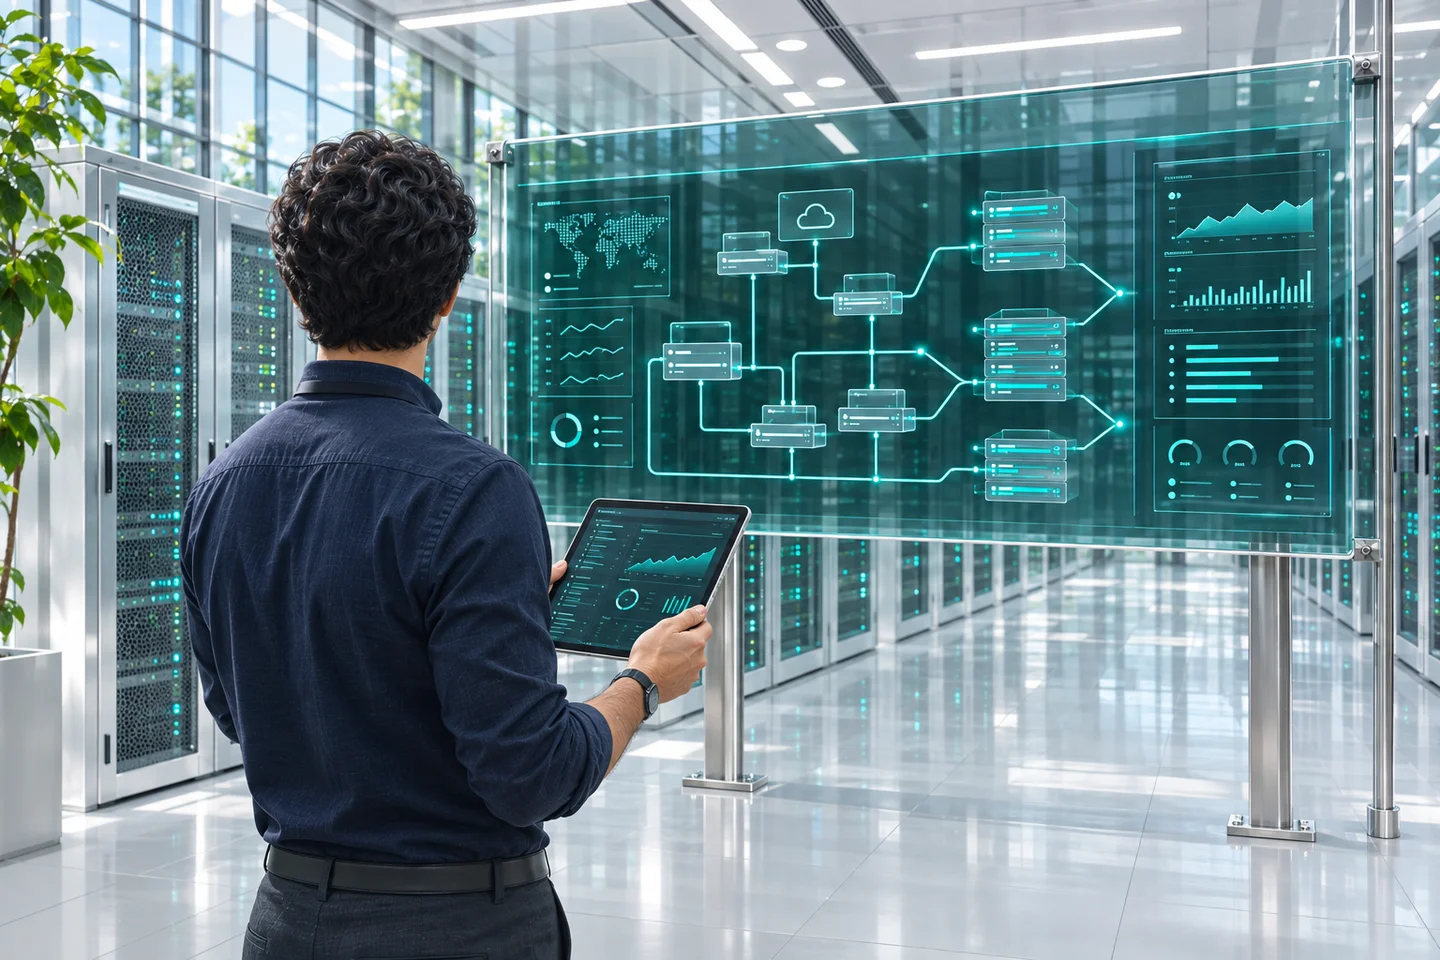
Map infrastructure, access and dependencies, with a named owner for the systems that matter most.
Connect logs and alerts to a response process, then verify targeted changes against the affected workload.
Review backup coverage, rehearse the agreed restore procedure and document the gaps that still need attention.
Start with the services people rely on, the incidents that repeat and the gaps in ownership. Prioritize changes that make operations easier to understand, support and recover.
COMMON STARTING POINTS
Map servers, cloud resources, networks and dependencies. Identify configuration, capacity and ownership gaps before changing the environment.
Connect useful logs, health checks and alert thresholds to named responders. Investigate recurring incidents and document escalation paths.
Review user and service accounts, permissions and access removal. Agree practical controls for administrative access and routine support.
Review backup coverage, retention and restore procedures. Rehearse recovery for agreed services and record what the exercise reveals.
Examine usage patterns, resource sizing and service dependencies. Identify changes to assess against performance, resilience and operating cost.
Create runbooks, maintenance routines and an escalation matrix. Define coverage, change approvals and responsibilities before ongoing support starts.
A business application slows down during its daily import. The engagement follows the workload from evidence gathering to a verified change and an operating procedure.
Capture timings, logs and resource usage. Map the application, database and scheduled jobs involved in the import.
Test the suspected bottleneck in a suitable environment. Agree the change, owner and recovery steps before deployment.
Repeat representative imports and compare results with the baseline. Check that other important workloads still behave as expected.
Document the fix, alerts and escalation path. Review the next maintenance window and the evidence needed if the issue returns.
The scope identifies the systems covered, access required and support responsibilities. Recommendations are prioritized by business impact and implementation effort.
An inventory of agreed services, their connections, access requirements and operational owners.
Observed issues, recommended changes, dependencies and a practical sequence for implementation.
Procedures for routine support, common incidents, maintenance and escalation, with named responsibilities.
Restore exercise findings, documented recovery steps and a review of outstanding risks and follow-up actions.
Clarify the scope, responsibilities and decisions behind a useful engagement.
Yes. We start with the environment you already operate, including cloud and on-premises dependencies. Access, ownership and change approvals are agreed with your team before implementation.
Support hours, escalation contacts, response expectations and any out-of-hours coverage are agreed for each engagement. They are defined explicitly in the support scope.
We review coverage and retention, agree recovery priorities and exercise the relevant restore procedure. The findings identify what was recovered, the time taken and any dependencies that still need attention.
Changes are planned around the affected services, dependencies and available maintenance windows. Testing, communication and a recovery approach are agreed before a production change; the expected impact is reviewed with you.
An initial review can establish the environment, priorities and operating procedures. We then agree which responsibilities stay with your team and which are included in an ongoing support arrangement.